Claude Code 团队怎么做代码评审
How do you review code at the volume agents produce it? On the Claude Code team, once we had high coverage and deep reviews, we started optimizing for the minimum amount of human review time that doesn't raise reverts or incidents.
Agent 产出代码的量这么大,评审怎么跟得上?在 Claude Code 团队,等覆盖率和评审深度都上去以后,我们开始追求另一件事:在回滚和事故不增加的前提下,把人花在评审上的时间压到最少。
We've said before that Claude writes about 90 percent of Claude Code's own code. So how do we review code at the volume we produce it? Does anyone read code anymore? And if something breaks, who catches it?
我们之前说过,Claude Code 自己的代码大约 90% 是 Claude 写的。代码产出到这个量,我们怎么评审?还有人读代码吗?出了问题谁来兜?
This post covers the code review flow on the Claude Code team and how it has evolved. From June to September, merged pull requests to Claude Code's codebase more than doubled while the share that had to be reverted fell by more than 40 percent.
这篇讲 Claude Code 团队的代码评审流程,以及它是怎么一步步变成现在这样的。从 6 月到 9 月,Claude Code 代码库合并的拉取请求(pull request,下文简称 PR)翻了一倍多,需要回滚(revert)的比例却降了 40% 以上。
We didn't remove review. But we did move most of the reading to machines, optimized for human time and attention, and invested heavily in making it fast and easy to undo mistakes.
评审我们没有取消。但大部分阅读交给了机器,一切围绕人的时间和注意力来优化,还下了大力气让出错能撤回得又快又容易。
Rethinking the purpose of code review重新想想代码评审是为了什么
When agents write code, the number of changes goes up, fast. In Anthropic's monorepo, changes landing per day went from about 2,500 in May to more than 30,000 in September this year.
Agent 一写代码,改动的数量就往上涨,涨得很快。在 Anthropic 的 monorepo 里,每天合入的改动从今年 5 月的大约 2,500 个涨到了 9 月的 30,000 多个。
Claude Code lives in its own repository, separate from the monorepo, but it's seeing a lot of pressure too. When you are shipping this fast, manual, line-by-line code review is incredibly difficult if not impossible.
Claude Code 有自己单独的仓库,不在 monorepo 里,压力一样不小。发布快到这个程度,靠人逐行评审就算不是做不到,也难得要命。
Code review does two jobs:
代码评审干两件事:
- Find and fix issues before they ship在问题上线之前找出来、修掉
- Build shared context and codebase understanding across the team让整个团队共享上下文,都懂这个代码库
This article mainly focuses on finding and fixing issues, but we will come back to the second job near the end.
这篇主要讲第一件,找问题和修问题,第二件快结尾时再说。
We think "did a human read the code?" is an imprecise proxy for "what could go wrong with this change, and which check—automated or human—is the right one to catch it?"
我们觉得,「有没有人读过这段代码?」只是个粗糙的替代指标。真正该问的是:「这个改动可能出什么问题?哪种检查,自动的也好、人工的也好,最适合把它抓出来?」
Asking that question also changed when review happens. Before, review was a gate at the end of the road: write the code, open a PR, wait for your colleague.
这么一问,评审发生的时间点也跟着变了。以前评审是路尽头的一道关卡:写完代码,开 PR,等同事来看。
Now, review runs continuously, more like spellcheck while you write. Most changes have been reviewed and fixed by Claude at least once before a human is asked to look. This catches most routine mistakes, and saves team attention for higher-level questions and scrutiny.
现在评审一直在跑,更像边写边查的拼写检查。大多数改动在请人看之前,已经被 Claude 评审并修过至少一轮。常规错误大多在这一步就被抓住了,团队的注意力就能留给更高层面的问题,看得更细。
The scarce resource: human time and attention稀缺的是人的时间和注意力
We want to preserve human time and attention for issues only humans can solve and make sure automated checks catch the rest. At our current rate of change, there is still an incredible amount of work for humans to do, and our team encounters new and novel challenges almost daily.
我们想把人的时间和注意力留给只有人能解决的问题,其余的确保都由自动检查抓住。照现在的改动速度,要人来做的事依然多得惊人,团队几乎每天都会撞上没见过的新难题。
Human time covers both sides of review's cost: the time people spend reviewing, and the time they spend fixing what bad code breaks. Cutting the first doesn't help if the time just shows up in the second.
人的时间包括评审成本的两头:花在评审上的时间,和花在收拾烂代码弄坏的东西上的时间。前一头省下来的时间要是又在后一头冒出来,那就白省了。
So the goal is that most pull requests in the Claude Code repos (the CLI, the desktop and web apps, and the mobile apps) merge with at most one human in the loop, who can be the author, with no increase in reverts or incidents. To measure human time, we track human approvals per PR (median and 95th percentile), human comments, and how long a PR waits on a person. Revert and incident rates are the guardrail: if they rise, we haven't saved human time, we've only moved it.
所以目标是:Claude Code 各个仓库(CLI、桌面端和网页端应用、移动端应用)里的大多数 PR,合并时环路里最多只有一个人,这个人可以就是作者本人,同时回滚和事故不增加。为了衡量人的时间,我们跟踪每个 PR 的人工批准数(中位数和第 95 百分位)、人工评论数,以及 PR 等人处理等了多久。回滚率和事故率是护栏:它们一旦上升,就说明我们没有省下人的时间,只是把它挪了个地方。
The life of a change一个改动的一生
A typical change, from an engineer's laptop (or a Claude session in Slack), goes through multiple layers of code review.
一个典型的改动从工程师的笔记本(或者 Slack 里的一个 Claude 会话)出发,要过好几层代码评审。
Layer by layer一层一层来
1. The work is verified before anyone else looks1. 别人看之前,活先验证好
Most review now happens before a PR exists. We give Claude something it can run—like tests, a build or a screenshot to compare against the design—and ask it to show the output instead of saying it's done. Then a subagent reviews the diff with fresh context. Both habits come from our best-practices guide.
现在大多数评审在 PR 出现之前就做完了。我们给 Claude 一个能跑的东西,比如测试、一次构建,或者一张拿来跟设计稿对比的截图,让它把输出亮出来,而不是光说一句做完了。然后再让一个子 agent(subagent)带着全新的上下文去评审 diff。这两个习惯都出自我们的最佳实践指南。
Before opening a PR, many of us also run a few internal skills: one hunts for bugs, one simplifies the diff, and one checks the behavior end to end. UI changes also get checked against our design guidelines.
开 PR 之前,我们很多人还会跑几个内部 skill:一个专门找 bug,一个精简 diff,一个端到端地检查行为。UI 改动还要对着我们的设计规范再查一遍。
Boris Cherny, who created Claude Code, has called giving Claude a way to verify its work probably the most important thing for getting good results. He estimates it makes the final result two to three times better, and writes, "Verification looks different for each domain. It might be as simple as running a bash command, or running a test suite, or testing the app in a browser or phone simulator."
Claude Code 的创造者 Boris Cherny 说过,想要好结果,给 Claude 一个验证自己工作的手段大概是最重要的一件事。他估计这能让最终结果好上两三倍,还写道:「每个领域的验证方式都不一样。可能简单到跑一条 bash 命令,或者跑一套测试,或者在浏览器、手机模拟器里把应用试一遍。」
When the automated reviewer keeps flagging the same thing, we fix it at the source: in the skill, with a lint rule, or with updates to instructional files such as:
自动评审老是标出同一类问题时,我们就从源头上修: 改 skill、加一条 lint 规则,或者更新指令文件,比如:
CLAUDE.mdtells Claude what the project is: the stack, the conventions, the goals and the non-goals. Every review loads it, so in a large codebase we keep it short and point to other docs from there. The reviewer also flags code that breaks a convention in it, and changes that make a line in it out of date.CLAUDE.md告诉 Claude 这个项目是什么:技术栈、约定、目标和非目标。每次评审都会加载它,所以在大代码库里我们把它写得很短,从这里再指到别的文档。评审器还会标出违反其中约定的代码,以及让其中某一行过时的改动。REVIEW.md, written by code owners, tells the reviewer what matters in their part of the code. We check separately whether the reviewer actually follows it. The good ones are short. They say what failure looks like in that repo (for docs it's "it lies," for config it's "it misroutes"), cap the nits, list paths to skip, and ask for a file and line as evidence instead of a guess from a name. They also ask for a summary that starts with a count and says plainly when there's nothing to fix.REVIEW.md由代码负责人(code owner)来写,告诉评审器在他们那块代码里什么最要紧。评审器到底有没有照着做,我们另外检查。写得好的都很短。它们会讲清楚在这个仓库里「出错」长什么样(文档是「它在说假话」,配置是「它把东西路由错了」),限制鸡毛蒜皮意见(nit)的条数,列出要跳过的路径,要求拿文件和行号当证据,而不是看个名字就猜。它们还要求总结以一个数字开头,没什么要修的时候就直说。
2. AI review on every pull request2. 每个 PR 都有 AI 评审
Every pull request gets a Claude review before a person looks. It reads the diff against the whole repo and the PR's stated intent, and asks: does the change solve its problem, fit the system, or break something else?
每个 PR 在人看之前,都会先过一轮 Claude 评审。它拿 diff 对照整个仓库和 PR 写明的意图来读,然后问:这个改动解决了它要解决的问题吗?跟系统合得来吗?会不会弄坏别的东西?
On a bug fix, it looks for the root cause. The public version, Code Review for Claude Code, is now generally available on Team and Enterprise plans, and /code-review runs a lighter version locally.
如果是修 bug,它会去找根因。公开版本 Code Review for Claude Code 现在已经在 Team 和 Enterprise 套餐上全面开放,/code-review 则是在本地跑一个轻量版。
When we launched the research preview, the share of internal PRs getting substantive review comments went from 16% to 54%. Most PRs over 1,000 lines get findings, and most small ones come back clean. Admins set each repo to Quick, Standard, or Deep. Deep is worth it where one missed bug costs more than the extra review time.
我们推出研究预览版的时候,内部 PR 里收到实质性评审意见的比例从 16% 升到了 54%。超过 1,000 行的 PR 大多会被查出问题,小 PR 大多干干净净地回来。管理员可以给每个仓库选 Quick、Standard 或 Deep。漏一个 bug 的代价要是比多花的评审时间还高,Deep 就值得。
Findings get verified by other agents before humans review them. Several agents look for bugs at the same time. Then a separate group votes on each finding, and it only gets posted if enough of them agree it's real. Findings that are only about style, diagnostics, or cleanup get dropped. We A/B tested those filters on our own PRs before keeping them. What's left shows up as inline comments sorted by severity. Each is tagged Important, Nit, or Pre-existing, so a bug the PR didn't introduce doesn't look like the author's fault.
人看之前,发现的问题先由别的 agent 核实。 好几个 agent 同时找 bug,然后另一组 agent 给每条发现投票,够多的 agent 都认定它是真问题才会贴出来。只关于代码风格、诊断信息或清理的发现直接丢掉。这些过滤规则是我们先在自己的 PR 上做过 A/B 测试才留下的。剩下的以行内评论的形式出现,按严重程度排序。每条都标着 Important、Nit 或 Pre-existing,这样一个不是这个 PR 引入的 bug,就不会看着像是作者的锅。
Every finding has to be answered. You either fix it or resolve the thread with a reason. Often an agent picks up the fix overnight, so the author comes back to a PR that's already been through another round.
每条发现都得有个回应。 要么修掉,要么写明理由把讨论串关了。很多时候会有 agent 连夜把修复接过去,作者回来一看,PR 已经又过了一轮。
3. Security review that can block3. 能拦住合并的安全评审
Security gets its own automated review too. A PR can't merge while any finding from the bug review or the security review is still open. You either fix it or close the thread with a short reason, which is how you clear a false positive.
安全也有自己的一套自动评审。只要 bug 评审或安全评审里还有一条发现没处理,PR 就合不进去。要么修掉,要么写一句简短的理由把讨论串关掉,误报就是这么清掉的。
If a later commit fixes the issue, the finding clears on its own. You can set up the same thing with the open-source security review GitHub Action or the /security-review command. Setup is covered in automated security reviews in Claude Code.
如果后面的提交把问题修好了,那条发现会自己消掉。你也可以用开源的安全评审 GitHub Action 或者 /security-review 命令搭一套一样的。怎么配见 Claude Code 中的自动安全评审。
4. Automated checks that block4. 能拦住合并的自动检查
The usual: lint, type checks, tests on every platform, and a build. (We wrote about scaling CI for this volume here.) A typical CLI pull request may run dozens of checks before anyone looks at it. The PR template asks how the change was tested and how to undo it. Claude can fill that in, but the person who asked for the change signs off on it.
就是常规那些:lint、类型检查、各个平台上的测试,再加一次构建。(我们怎么把 CI 扩到扛得住这个量,写在这里。)一个典型的 CLI PR 在有人看之前,可能已经跑了几十项检查。PR 模板会问这个改动怎么测的、怎么撤回。Claude 可以把它填好,但得由提出这个改动的人签字确认。
5. Human approval, scaled by risk5. 人工批准,按风险加码
A docs fix and an auto-updater change carry different risk, so they get different review.
改个文档和改自动更新器,风险不一样,评审自然也不一样。
| 风险 | 例子 | 人工批准 |
|---|---|---|
| 低 | 文档、文案、只在内部用的功能、藏在功能开关后面的新增改动 | 自动评审和安全检查都通过后,不需要 |
| 中 | 普通的产品改动,以及缓存、自动更新器、系统提示词这类敏感区域的改动 | 一个人 |
| 高 | 风险最高的代码,外加一小批永远要两个人的路径 | 两个人 |
The change sets the tier, not the author. A classifier reads the change and picks its risk tier. A second classifier asks whether this particular change needs another person even when its tier says it doesn't. Some paths always need a person, anything owners have listed as sensitive and any CI workflow file.
档位看改动,不看作者。 一个分类器读这个改动,给它定风险档位。第二个分类器再问:就算档位说不用,这个具体的改动是不是还得再多一个人看?有些路径永远需要人,包括负责人列为敏感的任何东西,以及所有 CI 工作流文件。
Only trusted authors get the lighter paths. Only authors on the repo's trusted list get the lighter paths, mostly the team that owns it. Everyone else needs a second person to approve. An agent's approval never counts as a person's, either. Automated review can clear a low-risk change, but it can't fill a slot that calls for a human.
只有受信任的作者能走轻量通道。 只有在仓库受信任名单上的作者才能走轻量通道,基本上就是负责这个仓库的团队。其他人都要第二个人批准。agent 的批准也永远不能算作人的批准。自动评审可以放行低风险改动,但需要人的那个位置,它补不上。
Whoever prompted the change is on the hook for it. On an agent-written PR, the person directing the agent counts as one of the required reviewers, the same as if they'd typed the code themselves.
谁让写的,谁担着。 agent 写的 PR 上,指挥 agent 的那个人算作必需的评审者之一,跟代码是他们自己一个字一个字敲出来的一样。
An approval covers one specific commit. If new commits land that the system can't vouch for, like an agent's push or a merge someone resolved by hand, the approval has to be given again.
一次批准只管一个具体的提交。 要是又进来了系统担保不了的新提交,比如 agent 推上来的提交,或者有人手动解决冲突的合并,就得重新批准。
6. Merge queue, flags and a gradual release6. 合并队列、功能开关和逐步发布
The merge queue re-runs every check against main with the change applied, so two PRs that pass separately can't combine into a broken main. New behavior usually ships behind a flag to Anthropic employees first, and our heavy use often surfaces regressions before users do. Public releases go to the latest channel first. The stable channel trails it.
合并队列(merge queue)会把改动应用到 main 上,把每项检查重跑一遍,这样两个各自都能通过的 PR 就不会合在一起把 main 弄坏。新行为一般先藏在功能开关(feature flag)后面,发给 Anthropic 员工用。我们用得很猛,回归问题常常在用户碰到之前就暴露了。公开发布先进 latest 频道,stable 频道跟在后面。
7. Fast detection, fast rollback7. 发现要快,回滚要快
Some mistakes will still get through, so the last layer is about catching them fast. Flags turn off without a deploy. Claude Code has a weekly on-call rotation, and incident reviews ask which layer should have caught the issue.
总还是会有错漏过去,所以最后一层要做的就是尽快抓住它们。功能开关不用部署就能关。Claude Code 有按周轮换的值班(on-call),事故复盘会问:这个问题本该由哪一层抓住?
Noticing a bad merge still depends on the author and on-call as well as the revert and incident dashboards. We don't yet have circuit breakers that tighten approval when those numbers move; engineers here want them before more code moves to zero-human merges.
发现一次坏的合并,现在还是得靠作者和值班的人,外加回滚和事故的看板。我们还没有熔断机制,能在这些数字一动的时候自动收紧批准要求;这里的工程师希望先把它做出来,再让更多代码走零人工合并。
One colleague said slowing down does lower your error rate, but mostly because you're doing less of everything. We'd rather get faster at noticing and fixing problems.
有位同事说,放慢速度确实能降低出错率,但主要是因为你干什么都干得少了。我们宁可在发现和修复问题上变得更快。
How we make the reviewer better我们怎么让评审器变得更好
Our code review process is constantly improving in a loop.
我们的代码评审流程是在一个循环里不断变好的。
Any incidents are now an eval. The team collected past PRs that caused incidents, with their fix-forwards and reverts, and had engineers who know that code confirm each bug and where it lived. The reviewer runs against that set daily.
现在每次事故都会变成 eval。 团队把过去引发过事故的 PR 收集起来,连同它们的前向修复(fix-forward)和回滚,再请熟悉那段代码的工程师逐个确认 bug 是什么、出在哪。评审器每天拿这个集合跑一遍。
We measure noise by watching what people do with the comments. It's easy to catch more bugs if you don't mind flagging a lot of non-bugs, so we need a check on that. We sort every comment the reviewer leaves by how the person on the PR responded: they fixed it, said it was wrong, said the behavior was intentional, or decided it didn't matter. We also run the reviewer on PRs we know are clean and count how often it reports something that would have led someone to make a harmful change. Our priority, written down, is catching real bugs first and cutting review rounds second.
噪音有多大,看人怎么处理评论。 要是不在乎标出一大堆不是 bug 的东西,多抓几个 bug 很容易,所以得有东西制衡。评审器留下的每条评论,我们都按 PR 上那个人的反应归类:修了、说它错了、说这个行为是故意的,或者觉得无所谓。我们还会拿确认干净的 PR 跑评审器,数它有多少次报出了会诱导人去做有害改动的东西。我们白纸黑字写下的优先级是:第一抓真 bug,第二减少评审轮数。
Noise costs more when the author is an agent. A person can wave off a nit in seconds. An agent fixes it, which means another commit and another round of review.
作者是 agent 的时候,噪音更贵。人几秒钟就能把一条 nit 打发掉。agent 会老老实实去修,于是又多一个提交、又多一轮评审。
Review has to converge. An agent author and an agent reviewer can keep each other busy indefinitely. One CLI PR went through more than fifty rounds of review and fixes overnight before its author stopped it.
评审必须收敛。 agent 作者和 agent 评审器能没完没了地互相找活干。有个 CLI PR 一夜之间来回评审、修复了五十多轮,最后是作者叫停的。
When we ran git blame on what the reviewer kept flagging, about 59% of it was code that had been there since the reviewer's first pass. The reviewer was rarely finding new bugs, it was finding a few more old ones each round.
我们对评审器反复标出的东西跑了一遍 git blame,发现大约 59% 是评审器第一轮时就已经在那儿的代码。评审器很少找到新 bug,只是每轮多翻出几个老的。
We made it worse ourselves. We'd gotten used to running several rounds by default, since each pass catches something new. This can be worthwhile on a risky change, but not on every PR. The team now tracks rounds-to-pass alongside recall, and changed re-review:
这事我们自己也推波助澜了。因为每一轮都能抓到点新东西,我们习惯了默认跑好几轮。有风险的改动这么做也许值得,但不是每个 PR 都该这样。团队现在把通过所需轮数(rounds-to-pass)和召回率(recall)放在一起跟踪,还改了重新评审的做法:
- A round cap. After three rounds, the reviewer asks the author to step back and reconsider the approach.轮数上限。 三轮之后,评审器会请作者退一步,重新想想思路。
- Diff-only re-review after the first few passes.前几轮之后,只对新的 diff 重新评审。
- Flag the class of bug, so the author fixes every instance, not one line.标出 bug 的类别,让作者把每一处都修掉,而不是只修一行。
- No repeats of findings already posted.贴过的发现不再重复。
Review agents also run nightly over existing code, helping us catch old bugs before they show up somewhere else.
评审 agent 每晚还会把现有代码过一遍,赶在老 bug 从别处冒出来之前把它们抓住。
Where humans stay in the loop人还守在哪些环节
Pulling a senior engineer out of deep work to catch a routine mistake costs far more than an automated review. People on the team are still responsible for:
为了抓一个常规错误把资深工程师从深度工作里拽出来,代价比一次自动评审高得多。团队里的人仍然负责这些:
- Deciding whether to build it. Direction, taste and scope. One team that declared its review bottleneck solved still kept human review for changes from outside the team, so someone asks "should we even do this?"决定要不要做。 方向、品味和范围。有个团队都宣布评审瓶颈解决了,对团队外部来的改动却仍然保留人工评审,好让有人问一句「这个我们到底该不该做?」
- Reviewing risky code such as billing, the auto-updater and CI workflows.评审高风险代码,比如计费、自动更新器和 CI 工作流。
- Reviewing architecture that sets a pattern others will copy.评审架构,那些会定下模式、让别人照着抄的设计。
- Reading the evidence. Test output, the command that ran and what it returned, a screenshot, the reviewer's findings. If you can't say what the checks would miss, ask for a real review rather than a quick approval.看证据。 测试输出、跑了什么命令和它返回了什么、截图、评审器的发现。如果你说不出这些检查会漏掉什么,就去要一次真正的评审,别草草批了。
- Owning the outcome. A person is accountable for every change that ships, whoever typed it.对结果负责。 每个上线的改动都有一个人担责,不管代码是谁敲的。
Sharing context across the team在团队里共享上下文
Code review's second job has always been to spread codebase understanding. Reading a teammate's diff is how you learn what changed and how the pieces fit. If machines do most of the reading, how does anyone learn the code?
代码评审的第二件事,一直是让大家都懂代码库。读队友的 diff,你才知道改了什么、各部分是怎么拼起来的。如果大部分阅读都交给了机器,人还怎么去了解代码?
We don't have a formal process for this. Nobody on the team keeps a complete mental model of Claude Code in their head, and we don't think anyone needs to. When someone wants to understand a part of the codebase, they ask Claude to write an explainer for exactly that slice. It takes minutes and reflects the code as it is today.
这件事我们没有正式的流程。团队里没有谁脑子里装着 Claude Code 完整的心智模型,我们也不觉得谁需要装。有人想弄懂代码库的某一块,就让 Claude 专门针对那一块写一份讲解。几分钟就好,讲的是代码今天的样子。
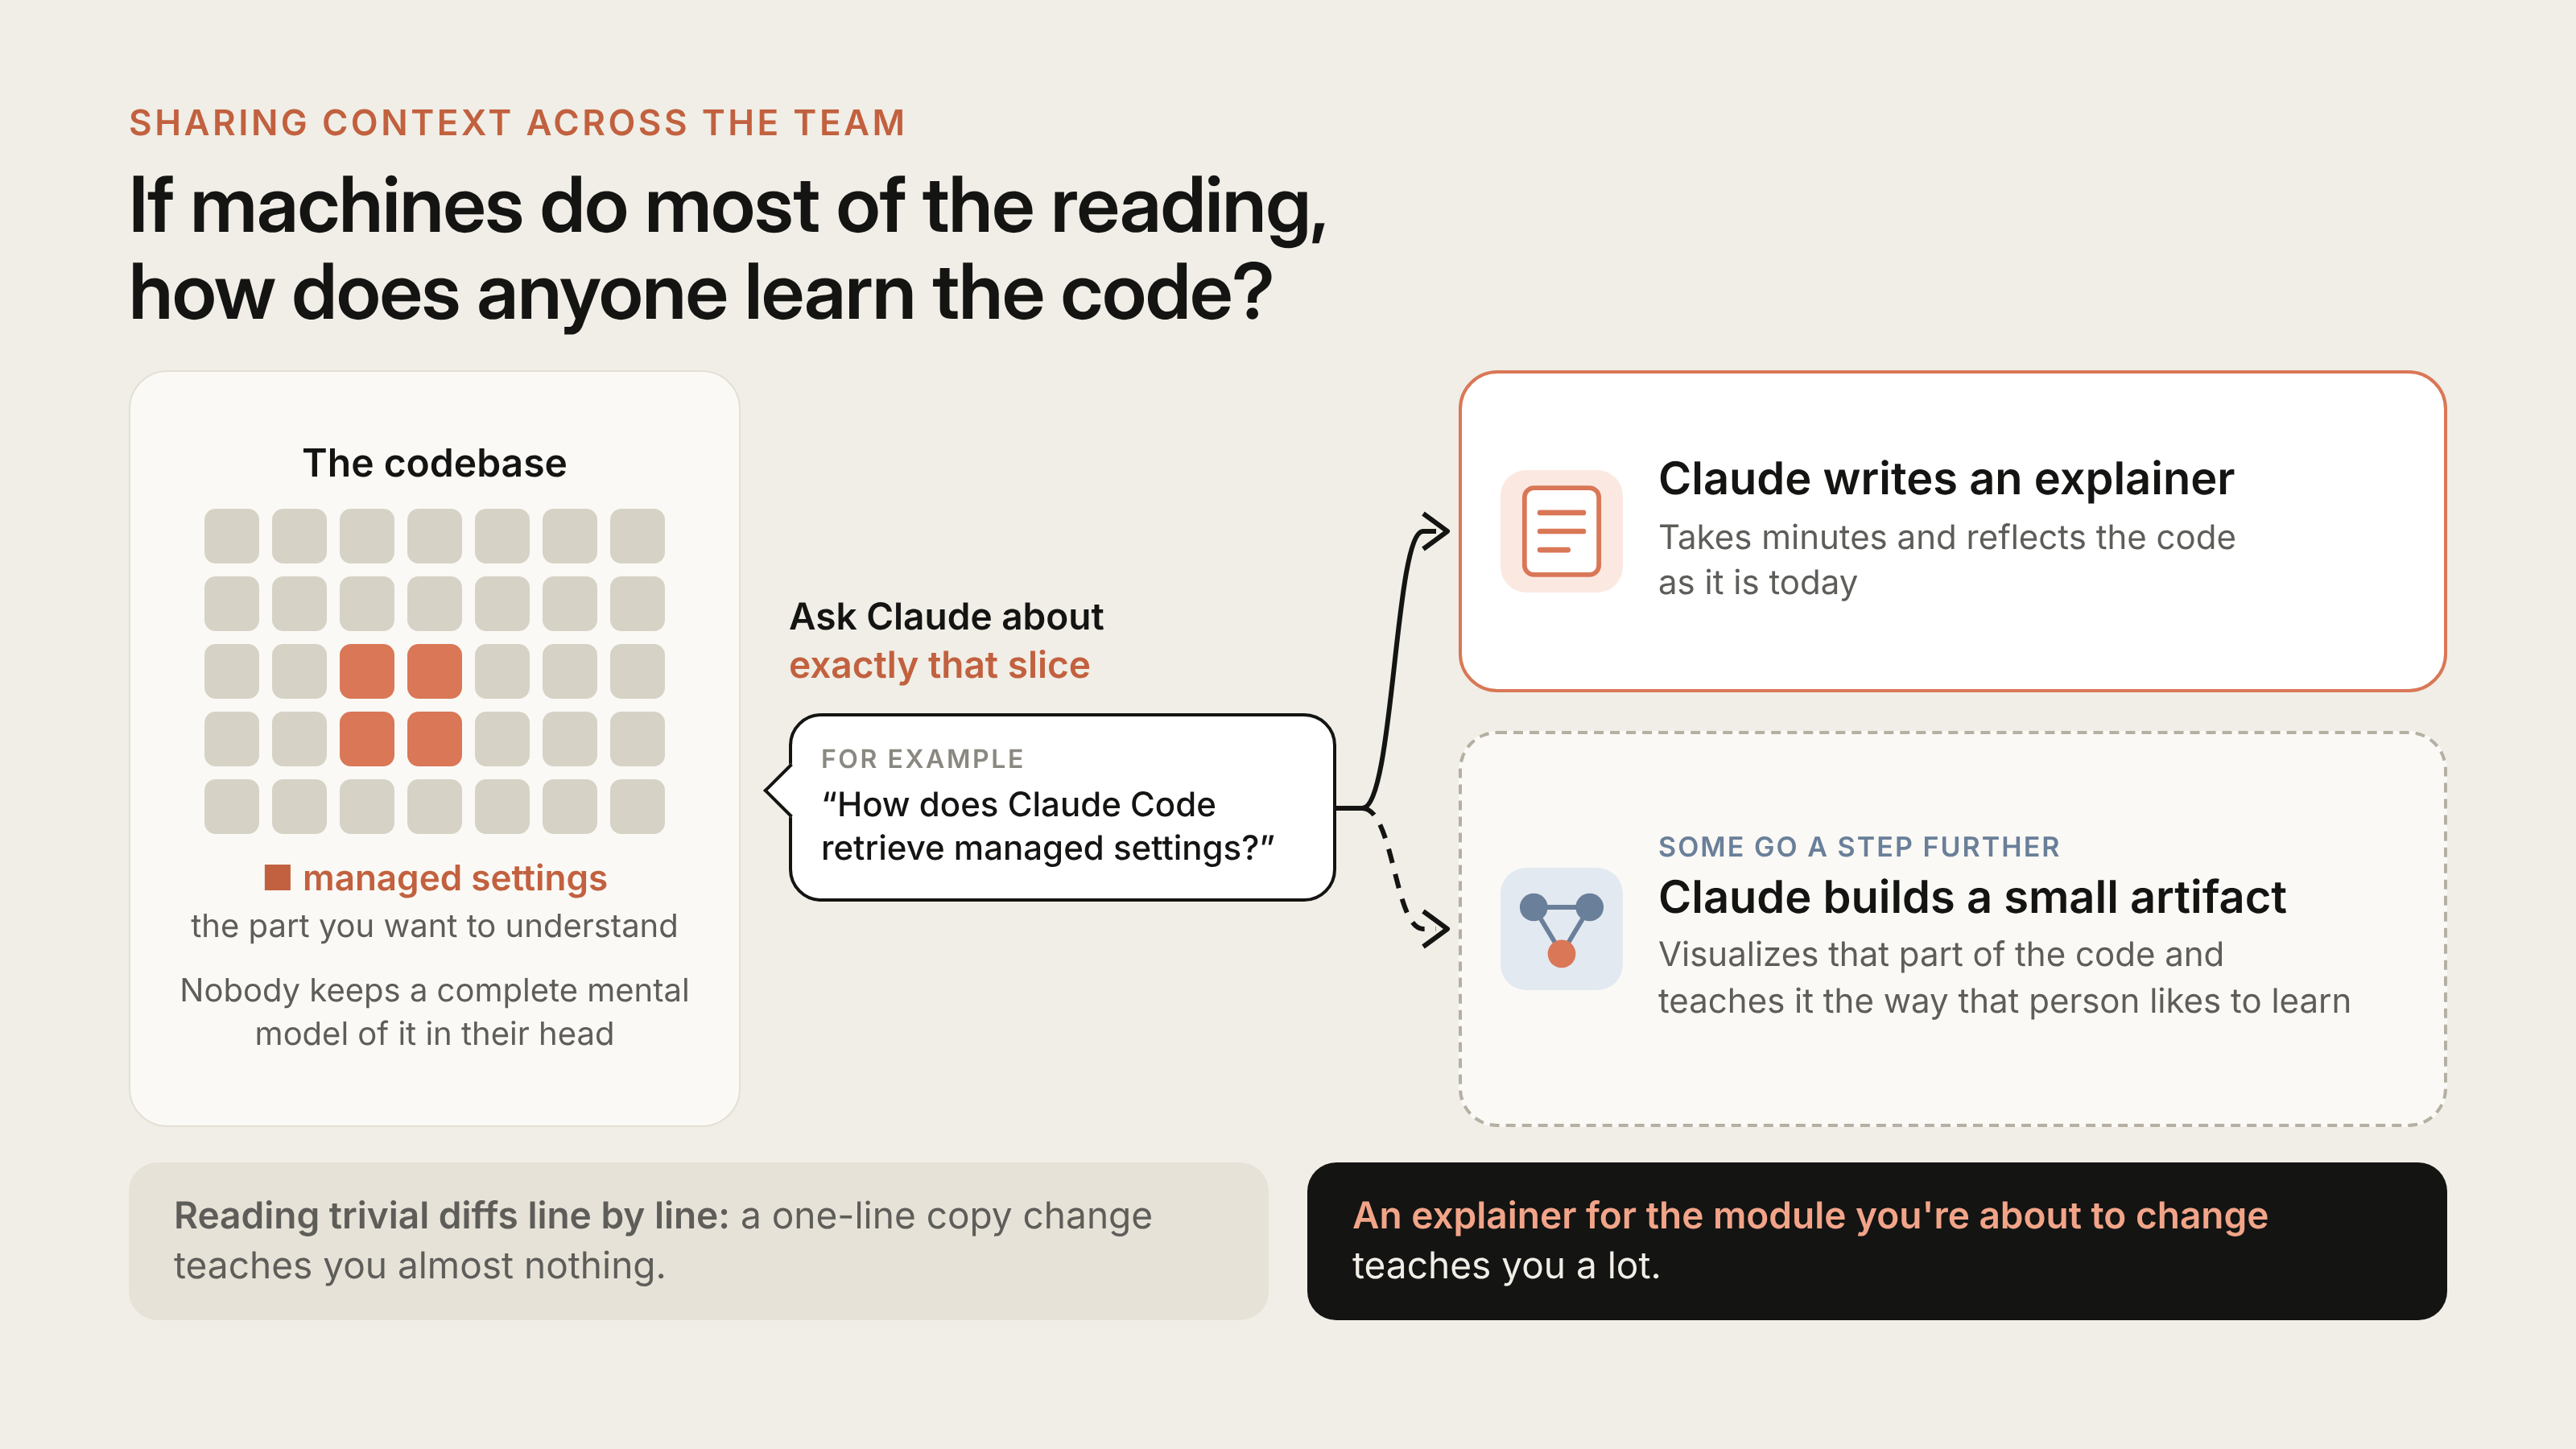
Some of us go a step further and have Claude build a small artifact that visualizes that part of the code and teaches it the way that person likes to learn.
我们有些人会再进一步,让 Claude 做一个小 artifact,把那部分代码可视化,按这个人喜欢的学习方式来讲。
If the goal is to spend human attention well, this beats reading trivial diffs line by line. A one-line copy change teaches you almost nothing. An explainer for the module you're about to change teaches you a lot. Our culture of defaulting to working on open Slack channels helps too, since you see what others are building while they build it.
如果目标是把人的注意力花在刀刃上,这比逐行读琐碎的 diff 强得多。改一行文案的 diff 几乎教不了你什么。你马上要改的那个模块的讲解,能教你很多。我们默认在公开 Slack 频道里干活的文化也帮了忙:别人在做什么,你在他们做的时候就看得见。
"You land it, you own it"「谁合进去的,谁负责」
If you land a small or medium change and something still goes wrong, it's a team norm that you usually fix it. A few things keep this from going badly:
你合入了一个小型或中型改动,结果还是出了问题,那按团队惯例,一般由你来修。有几件事让这条规矩不至于变味:
- Changes are small, so they're easy to review, debug and revert.改动都很小,所以好评审、好调试、好回滚。
- Everything is reversible. Flags, reverts and staged releases undo most mistakes in minutes.什么都能撤回。 功能开关、回滚和分阶段发布,能在几分钟内撤掉大多数错误。
- Blast radius sets the bar. Expensive code gets more people and more checks.影响范围(blast radius)决定门槛。 出错代价高的代码,要更多人、更多检查。
- Regressions surface fast through telemetry and internal use.回归问题暴露得快,靠遥测和内部使用。
- It isn't blame. Owning a fix means you have the most context; incident reviews look at the system.这不是追责。 由你来修,是因为你手里的上下文最多;事故复盘看的是系统。
Ownership is also shared. Much of the team works in open channels where anyone can see what others are building, pick up a thread, or point a Claude at a gap, and feedback comes from people who don't own the code too. That openness is a big part of how quality stays high without a gate on every line.
责任也是大家共担的。团队里很多人在公开频道里干活,谁都能看到别人在做什么,可以接过一条线索,或者派一个 Claude 去补某个缺口;反馈也会来自不负责这块代码的人。不给每一行都设关卡还能把质量守住,很大程度上靠的就是这种开放。
When we change direction需要掉头的时候
Agents make it cheap to start things, so some work shouldn't land. Usually someone in the channel asks why, points at an earlier decision, or suggests a simpler route, and the author closes or reshapes the PR.
有了 agent,开个头变得很便宜,所以有些活本来就不该合进去。通常是频道里有人问一句为什么,指出之前做过的某个决定,或者提一条更简单的路,然后作者就把 PR 关掉或者重新调整。
Since the code was fast to write, closing the PR doesn't feel like a loss. The trick is to raise a different direction in the thread early, not as a blocking comment on a finished PR.
代码本来就写得快,关掉 PR 也不觉得心疼。诀窍是早点在讨论串里提出别的方向,别等 PR 都做完了再甩一条拦路的评论。
How you can adopt this process你可以怎么用上这套流程
Most of the pieces to do this with your team exist today.
在你自己团队里这么做,需要的零件今天大部分都已经有了。
Before the pull request开 PR 之前
- Give your agent checks it can run, listed in a short
CLAUDE.md, plus hooks that run formatters and linters.给你的 agent 一些它能跑的检查,列在一份简短的CLAUDE.md里,再加上跑格式化工具和 linter 的 hook。 - Run
/code-reviewand/security-reviewlocally, or a fresh-context subagent review.在本地跑/code-review和/security-review,或者让一个带全新上下文的子 agent 来评审。 - Add a
REVIEW.md, and move repeated review comments into it.加一份REVIEW.md,把反复出现的评审意见挪进去。
On every pull request每个 PR 上
- Require CI, and add "Testing", "Risk" and "How to revert" to your PR template.强制要求 CI,在 PR 模板里加上「测试」「风险」和「如何撤回」三项。
- Add an AI reviewer (Code Review for Claude Code, or the Claude Code GitHub Action) on one repo, tune
REVIEW.mdfor a few weeks, then widen.先在一个仓库上加 AI 评审器(Code Review for Claude Code,或者 Claude Code GitHub Action),花几周调REVIEW.md,再铺开。 - Add automated security review, and require every review thread resolved before merge.加上自动安全评审,要求合并前所有评审讨论串都已解决。
- Match review effort to risk: a quick pass on routine changes, a deep one where a missed bug is expensive (Quick, Standard or Deep in Code Review).让评审投入跟风险匹配:常规改动快速过一遍,漏一个 bug 代价高的地方就深挖(对应 Code Review 里的 Quick、Standard 或 Deep)。
- Cap review rounds; after the first few, re-review only the new diff.给评审轮数设上限;前几轮之后,只重新评审新的 diff。
Approval批准
- Write down risk tiers, set from the change rather than the author; start strict and loosen with evidence.把风险档位写下来,按改动而不是按作者来定;一开始从严,有了证据再放宽。
- Keep the lighter approval paths for authors you trust.轻量的批准通道只留给你信得过的作者。
- Use CODEOWNERS and branch protection so auth, billing, CI and release workflows, and installers always need a person.用 CODEOWNERS 和分支保护,让鉴权、计费、CI 和发布工作流、安装程序永远需要人来批。
- Never let a bot's approval replace a required human's; dismiss approvals on new commits.绝不让机器人的批准顶替必需的人工批准;有新提交就作废已有的批准。
Merge and after合并及之后
- Use a merge queue, feature flags, internal use first, staged releases and one-step rollback.用上合并队列、功能开关、先内部使用、分阶段发布和一步回滚。
- Turn incidents and reverts into an eval set, and rescore the reviewer whenever its prompts, tools or model change.把事故和回滚做成 eval 集,评审器的提示词、工具或模型一变就重新打分。
- Measure human time, with revert and incident rates as the guardrail.衡量人的时间,拿回滚率和事故率当护栏。
Where this is going接下来往哪走
Code Review's announcement said approving a pull request is still a human call; the product posts findings, not approvals. Our own repos go further, letting owners decide which low-risk changes merge on automated checks alone, and that line keeps moving.
Code Review 的发布公告里说过,批不批一个 PR 仍然由人拍板;这个产品贴出来的是发现,不是批准。我们自己的仓库走得更远,让负责人决定哪些低风险改动单凭自动检查就能合并,而且这条线还在往前挪。
When a review misses something, we ask what the model didn't have in front of it and put the fix into a CLAUDE.md, a skill or a new check. The goal hasn't changed: less human time per change, and no more reverts than before.
评审漏了东西,我们就问:模型当时手边缺了什么?然后把修复放进 CLAUDE.md、某个 skill 或者一项新检查里。目标一直没变:每个改动少花人的时间,回滚不比以前多。
If your team lets agents open pull requests, we'd like to hear which checks you've automated, which still need a person, and what you think we have wrong.
如果你的团队也让 agent 开 PR,我们很想听听:你们自动化了哪些检查,哪些还得靠人,以及你觉得我们哪里做错了。
With thanks to Emma Webb, Michael Segner and Amie Rotherham for their reviews.
感谢 Emma Webb、Michael Segner 和 Amie Rotherham 帮忙审阅。